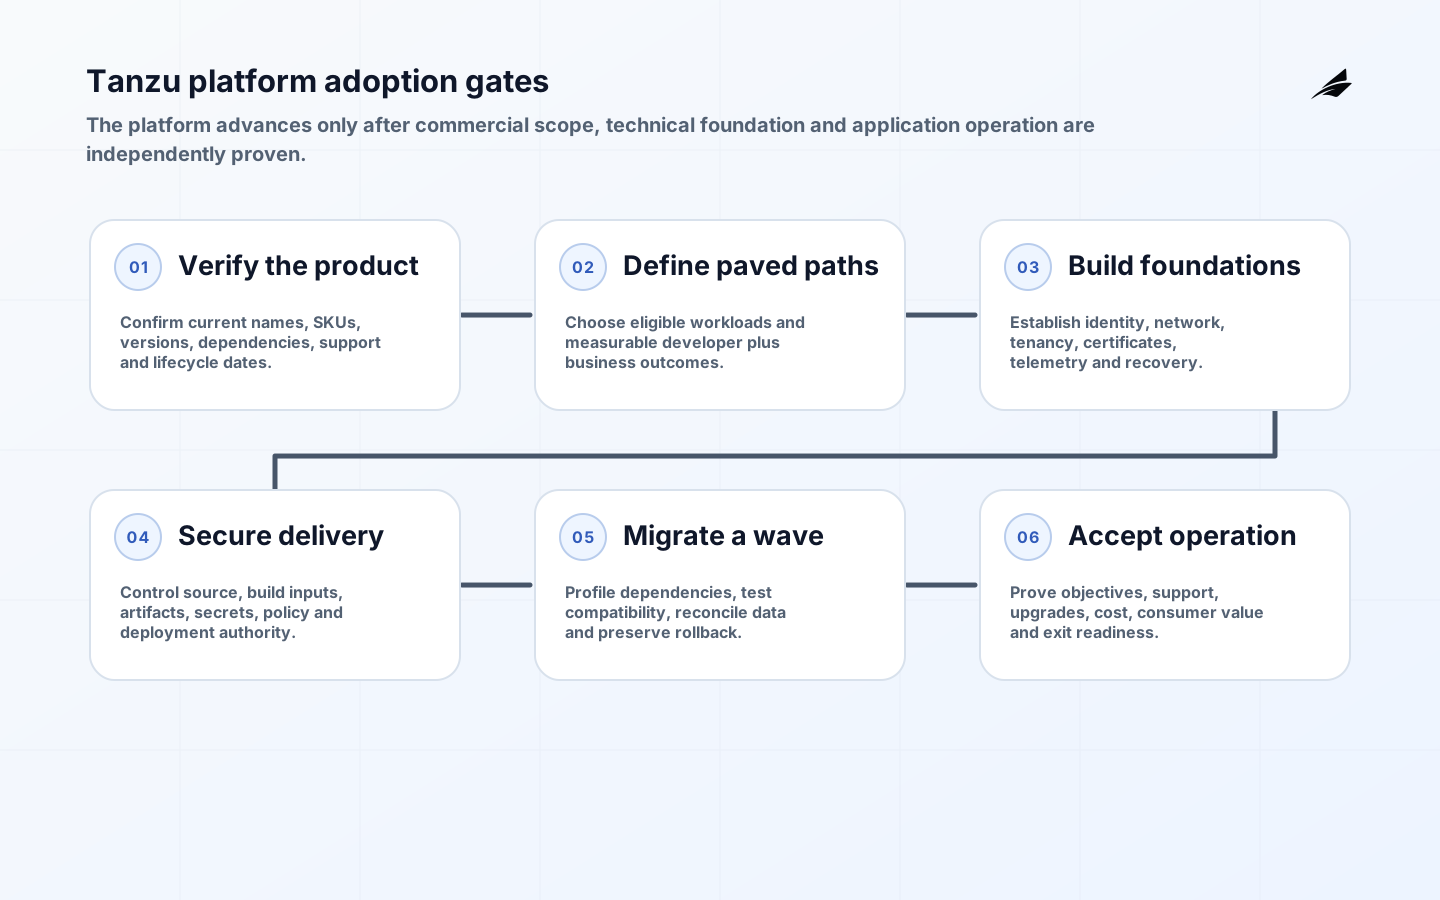
Enterprise Kubernetes application platform implementation begins with scope and version clarity. “Kubernetes platform” can mean a managed cloud service, a commercial distribution, a self-assembled stack or a mixture, and component names, bundles and release channels change over time. A reliable program verifies the exact entitled components, deployment model, supported versions and responsibilities before architecture or migration commitments. The business outcome is an operated application platform that gives developers a paved path while platform teams retain governance, reliability, security and lifecycle control.
This checklist complements the enterprise Kubernetes application platform FAQ and broader business process services checklist. Financial organizations should layer in the financial services implementation checklist. Because licensing, naming and support can change, confirm every commercial and compatibility statement against the current order, support portal and documentation for the contracted release.
Verify platform components, entitlements and support scope
Record component names, SKUs, versions, metrics, environments, infrastructure prerequisites, support level, end dates and dependencies. Suppliers rename and regroup components as portfolios change, so preserve old and new identifiers in the inventory because automation, downloads and operational records may use different names.
Obtain an entitlement and compatibility review from authorized sources. Test access to binaries, patches, security advisories and support before the program depends on them. Define who owns hypervisor or cloud, network, load balancing, DNS, certificates, identity, platform control plane, runtime, data services, build tooling or images, applications and observability. Do not infer responsibility from a bundled product name.
| Scope decision | Evidence | Owner | Stop condition |
|---|---|---|---|
| Exact components | Order, entitlement and current name mapping | Commercial owner | Ambiguous SKU or metric |
| Compatibility | Supported version matrix and dependency test | Platform architect | Unsupported combination |
| Infrastructure | Capacity, network, DNS and certificate proof | Infrastructure owner | Unresolved shared responsibility |
| Support | Case access, severity and escalation exercise | Service manager | No authorized support route |
| Lifecycle | Upgrade and end-of-support calendar | Platform product owner | No funded upgrade path |
Define the platform product and developer outcome
Choose representative applications and measure current lead time, deployment friction, security work, reliability and support burden. Define the paved path: supported languages, build inputs, services, environments, policy, telemetry and support. Platform adoption should reduce cognitive load and variation for suitable workloads, not force every application into one runtime. Publish eligibility and exception criteria.
Platform suppliers commonly describe application-centric abstractions, service binding and fleet visibility across clusters. Treat those as capabilities to verify in the contracted release, with the supplier's release notes retained in the evidence file. Demonstrate a source-to-running application path, credentials, policy, logs, traces, scaling and rollback using the organization’s identity and network constraints.
Design foundations, tenancy and failure domains
Map management, control and workload planes; availability zones; networks; routing; certificates; image or build sources; registries; secrets; databases; backups; telemetry and external dependencies. Define production failure domains and management recovery. Kubernetes production guidance stresses secure multi-user access, availability and capacity. Teams adopting a commercial distribution or add-on layer should also read the upstream Kubernetes documentation to understand the concepts behind it.
Choose tenancy from trust, blast radius, regulation, performance and cost. Namespaces or projects provide organization but not automatically sufficient isolation. Kubernetes multi-tenancy guidance notes security, fairness and noisy-neighbor concerns and recommends restrictive network defaults for strict isolation. Test control-plane and data-plane boundaries instead of relying on labels.
Secure identity and the application supply chain
Federate administrators and developers, use least privilege, time-limit elevation and separate platform, application and deployment roles. Inventory workload identities and service bindings. Keep credentials out of manifests and pipelines. Define certificate issuance, rotation and revocation. Audit administrative APIs, application access and service provisioning to a protected destination with synchronized time.
Approve source, build tooling, base images, dependencies, registries and artifact promotion. Rebuild or patch when supported inputs change, and prove that old vulnerable instances are replaced. Scan code, configuration and artifacts according to risk. Generate inventories and preserve provenance where available. Separate artifact creation from production deployment, protect pipeline changes and require independent approval for high-consequence services.
Migrate applications through evidence-based waves
Profile application runtime, language, state, routes, data, background work, integrations, certificates, scaling, logs and recovery. Select rehost, replatform, refactor, retain or retire deliberately. Run a compatibility spike for uncertain workloads. Group waves by dependency and business tolerance, not application count. Define rollback before changing data or routes.
Start with one production-representative vertical service. Build, deploy, bind dependencies, exercise failure, scale, update, rotate credentials, restore and observe it. Reconcile data and transactions at cutover. Keep old and new paths long enough for validated rollback where feasible, with a clear authority to invoke it. Retire legacy capacity only after operational acceptance and retention obligations are met.
| Gate | Required proof | Operational question | Decision |
|---|---|---|---|
| Foundation | Identity, network, certificates, logs and backup | Can the platform itself recover? | Proceed or repair |
| Golden path | Representative app through build and deploy | Can a team use it without expert intervention? | Adopt or redesign |
| Security | Policy, isolation, secrets and artifact evidence | Are boundaries enforceable? | Approve or constrain |
| Migration | Functional, performance and reconciliation tests | Can traffic move and return safely? | Cut over or pause |
| Operation | SLO, alerts, runbook, restore and support | Can on-call own the service? | Accept or extend hypercare |
Operate upgrades, capacity and platform services
Define service objectives for platform API, deployment, routing and critical backing services. Monitor user journeys, control-plane health, certificate expiry, capacity, failed builds, queueing and telemetry loss. Set quotas and chargeback or showback that encourage efficient requests without causing hidden throttling. Maintain support escalation and a status communication route for application teams.
Rehearse upgrades in a representative environment, read component advisories, back up required state and define abort criteria. Test application compatibility, build inputs and integrations. Use canaries or phased clusters where supported. Record configuration drift and emergency changes. Budget lifecycle work as platform product capacity; deferred upgrades can turn a supported paved path into a migration emergency.
Measure adoption, value and exit readiness
Track eligible workloads, successful self-service tasks, lead time, failed deployments, platform-caused incidents, developer support, patch time, unit cost and satisfaction. Segment by workload type. High application count does not prove value if teams bypass the platform or operations remain manual. Review the roadmap with consumers and retire unused services.
Keep application manifests, data exports, route and certificate inventories, deployment pipelines and runbooks portable enough for recovery and transition. Test export and replacement for critical backing services. Contract and architecture should avoid supplier-only ownership of identities, keys or repositories. Exit readiness is leverage for sound lifecycle decisions even when no migration is planned.
Run a production-representative platform pilot
Select two applications with different but supported needs: a stateless web service and a worker using a managed backing service. Baseline build and release time, support contacts, patch effort and recovery. The pilot provisions developer access through enterprise identity, builds from approved inputs, binds services without exposing credentials, deploys through the target network and exports telemetry to existing operations. Platform engineers document every manual exception and unclear component responsibility.
Exercise a base-image update, certificate rotation, application rollback, availability-zone failure and backing-service restore. Confirm the exact component support route by opening a noncritical case. Measure whether an application team can diagnose failure using the provided path without platform administrator access. Test quotas and isolation under noisy load. A successful deployment alone is insufficient because the platform will spend most of its life being patched, supported and changed.
Conclude with an evidence review covering workload fit, developer effort, control coverage, reliability, infrastructure capacity, license consumption and continuing platform labor. Decide which application classes enter the next wave and which remain elsewhere. Turn pilot exceptions into roadmap items with owners and dates. If a core dependency lacks a supported upgrade route, pause expansion rather than multiplying future migration pressure.
- Verify every pilot component against current entitlements and compatibility.
- Include operations, security and application teams in acceptance.
- Test lifecycle events, not only the first deployment.
- Use observed effort and consumption to update the business case.
Define the platform team’s own operating model before adding application waves. Maintain a consumer-facing roadmap, service objectives, incident rota, capacity forecast and security advisory process. Application teams need a clear route for unsupported frameworks, urgent patches and platform-caused incidents. Platform changes should use the same staged release discipline expected of applications. Regular consumer research can reveal whether a documented self-service path actually reduces wait time or merely moves complex diagnosis onto developers.
Financial acceptance should include license metric, infrastructure reservation, data-service consumption, support labor and upgrade environments. Model expected and peak demand plus the cost of retaining legacy platforms during migration. Unit measures such as cost per eligible application or successful deployment are imperfect but more actionable than total platform spend. Review them with reliability and developer effort so cost pressure does not encourage unsafe consolidation or under-provisioned shared services.
Key takeaways
- Verify current component names, versions, entitlements and support before design.
- Treat the Kubernetes platform as an owned product with explicit workload eligibility.
- Prove tenancy, identity, supply chain and recovery in the real environment.
- Migrate in dependency-aware waves with tested reconciliation and rollback.
- Fund upgrades, consumer support, value measurement and transition readiness.
Frequently asked questions
Is a Kubernetes distribution the same as an application platform?
Not universally. A distribution or managed service supplies working clusters; an application platform adds build, deployment, policy, service and operational layers on top. Verify which layers are contracted, which are open source add-ons and which the enterprise builds itself; do not use “Kubernetes” as a substitute for architecture or entitlement detail.
Should every application move to the platform?
No. Establish eligibility from runtime fit, lifecycle, data, isolation, performance and economics. Retaining, retiring or using another approved platform can be the correct decision for some workloads.
Conclusion
Enterprise Kubernetes application platform implementation succeeds through verified scope and operated platform evidence. Confirm the components, design a reliable foundation, secure the supply chain, prove a golden path, migrate cautiously and own upgrades. That discipline turns a shifting set of product names into a platform capability teams can actually depend on.