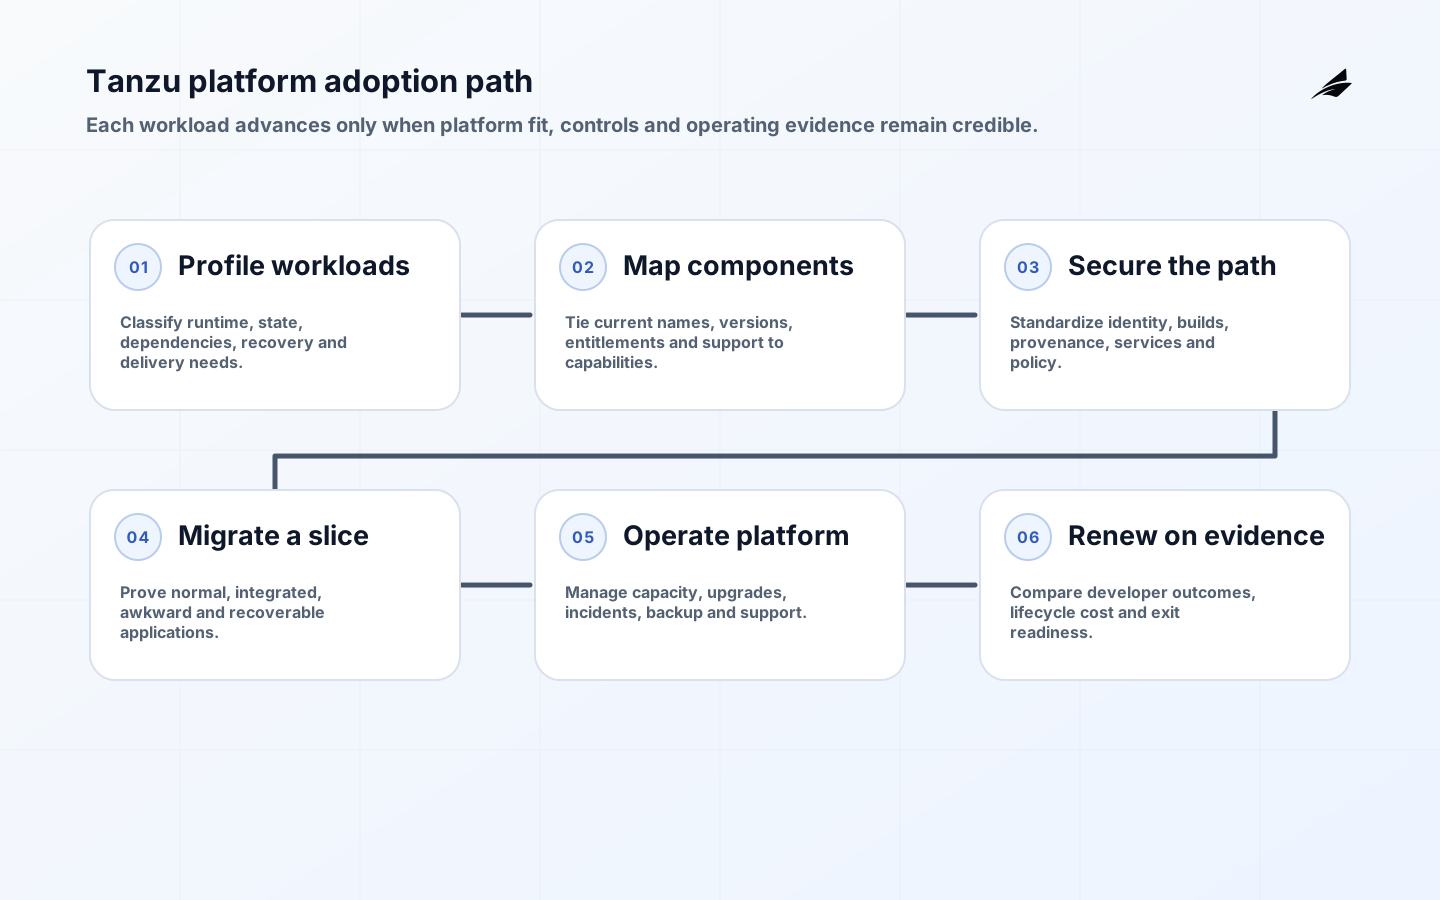
This enterprise Kubernetes application platform FAQ explains what buyers and platform teams need to decide before treating a Kubernetes-based platform as a standard route to production. An application platform is not one interchangeable hosting product. It is a set of capabilities and an operating model for building, deploying and managing applications across private-cloud and public-cloud environments. A sound decision starts with workload needs, platform responsibilities and lifecycle evidence, then tests whether the selected components reduce developer toil without hiding operational risk.
For a gate-by-gate rollout, use the enterprise Kubernetes application platform implementation checklist. Teams comparing operating transitions should also read the application management services checklist and the AWS implementation checklist. Product names and entitlements change, so procurement records should identify versions, components, support terms and authoritative documentation rather than relying on an old suite label.
What is an enterprise Kubernetes application platform?
An enterprise Kubernetes application platform is an internal product that standardizes application delivery on top of Kubernetes while giving platform operators governance and visibility. Platform teams can offer approved application runtimes, service bindings, build paths and operational policies; developers can focus on application code and declared dependencies. The value is a supported paved road, not merely a portal. It should shorten lead time, make routine controls repeatable and create a consistent ownership boundary between application and platform teams.
A typical platform combines cluster lifecycle management, an application runtime or deployment abstraction, build and supply-chain tooling, service routing, observability, policy, data and messaging services and a self-service interface. Exact packaging matters, because suppliers regroup and rename components over time. A proposal should map every promised capability to its current orderable component, version, metric, environment and support obligation.
| Decision area | Question to settle | Evidence to request |
|---|---|---|
| Runtime | Which application types and deployment models are in scope? | Supported stacks, versions, limits and test deployment |
| Developer path | What does a team do from commit to production? | Repository template, build record, policy gates and release trace |
| Operations | Who patches platform and application layers? | Responsibility matrix, maintenance method and escalation path |
| Services | How are databases, messaging and secrets bound? | Catalog, credential lifecycle and restore test |
| Commercial | What unit and support terms apply? | Current program documentation, quantities and renewal assumptions |
How do opinionated runtimes and Kubernetes fit together?
An opinionated platform-as-a-service runtime offers an application-centric experience: developers push code, the platform stages it, schedules instances, routes traffic and manages health. Kubernetes exposes lower-level workload and control-plane constructs and supports a broader ecosystem, but that flexibility can transfer more design work to each team. An internal platform on Kubernetes aims to provide an application-centered abstraction over those constructs. The correct choice follows application requirements, existing skills, portability needs and the organization's willingness to operate each layer.
Do not make runtime choice an ideological contest. Classify workloads by protocol, state, scaling behavior, network dependency, recovery objective, hardware need and release pattern. A conventional stateless web service may gain from an opinionated runtime; a specialized controller or workload requiring Kubernetes APIs may need Kubernetes directly. Preserve a documented exception route. If every exception becomes a custom platform, the paved road has failed; if no exception is possible, teams will work around it.
How are applications built and secured?
Platforms commonly use managed build mechanisms and can use Cloud Native Buildpacks to transform application source into runnable images without each team maintaining a bespoke Dockerfile. The Buildpacks documentation explains builder, buildpack, lifecycle and image concepts. Enterprises should pin trusted builders, record buildpack and dependency versions, produce software bills of materials, sign promoted artifacts and define how base layers are patched. Rebuilding after a vulnerability is only useful when teams can identify affected artifacts and promote replacements safely.
Separate platform security from application security. Platform operators protect clusters, control planes, identity integration, networks, build services, service brokers and logs. Application teams remain responsible for code, dependencies, authorization, data handling and business abuse cases. Use least privilege for namespaces, projects, service instances and automation credentials. Test tenant isolation and secret rotation. A single sign-on integration does not prove that application-to-service permissions or emergency administration are appropriately bounded.
| Control layer | Platform owner evidence | Application owner evidence |
|---|---|---|
| Identity | Federation, role model, break-glass test | Group mapping and least-privilege review |
| Supply chain | Trusted builder, provenance, signing and scanning | Dependency policy and remediation ownership |
| Network | Ingress, egress, segmentation and certificate lifecycle | Required flows and application authorization |
| Data service | Provisioning policy, encryption, backup and patching | Classification, retention and restore acceptance |
| Incident | Platform telemetry and supplier escalation | Application signals, customer impact and runbook |
What does day-two operation require?
A Kubernetes application platform is a production service. It needs capacity forecasting, high-availability design, certificate and secret renewal, vulnerability response, backups, restore exercises, platform upgrades and dependency monitoring. Establish service objectives for deployment success, application availability, route health and service provisioning. Monitor developer-facing symptoms as well as infrastructure. A healthy control plane does not help when builds queue for hours or a service broker cannot complete binding operations.
Treat upgrades as recurring product work. Maintain a supported-version calendar, release-note review, representative staging cluster and application compatibility suite. Kubernetes and the add-ons around it keep evolving, and suppliers are adding newer capabilities such as agent-oriented functions. New features should enter through architecture and risk review rather than being enabled automatically. Rehearse rollback and recover configuration from controlled definitions, not from an administrator's memory.
How should an enterprise migrate to a Kubernetes platform?
Inventory applications before selecting a migration factory. Capture runtime, build process, dependencies, data stores, network flows, identity, certificates, batch jobs, recovery objectives and current incidents. Group applications into retire, retain, rehost, replatform and refactor paths. A deployment that succeeds is not migration acceptance. Validate user journeys, data reconciliation, performance, observability, support readiness and rollback under realistic load.
Start with a representative slice, not only the easiest application. Include a normal stateless service, a service integration, an awkward dependency and an application with meaningful recovery needs. Measure elapsed migration effort, lead time after migration, build reliability, patch speed, platform tickets and developer cognitive load. Use the upstream Kubernetes and platform documentation to translate platform concepts into explicit operating tasks. Retire old routes, credentials and environments after reconciliation rather than paying indefinitely for a hidden fallback.
How should cost and value be evaluated?
Model subscription and support, infrastructure, platform engineering, upgrade work, observability, backup, network, training and migration. Then compare the total with avoided team-level tooling, faster release, reduced patch effort, better utilization and fewer incidents. Platform value is shared, so a chargeback model based only on raw compute can punish adoption. Showback should distinguish common platform cost from workload consumption and exceptional support.
Track adoption with quality. Useful measures include eligible applications onboarded, median commit-to-production time, successful deployment rate, time to remediate critical platform dependencies, service provisioning time, change failure, recovery time and satisfaction by developer role. Avoid celebrating deployments, logins or catalog size alone. A smaller set of well-supported paths with strong reuse can create more enterprise value than a broad catalog that shifts unresolved choices to developers.
Practical example: standardizing a service path
Consider a hypothetical enterprise whose internal services are split across manually maintained virtual machines and a small Kubernetes estate. The first platform cohort includes a stateless lookup API, a service that binds to a managed database, a batch reconciliation job and one service with a legacy certificate dependency. The team records current deployment time, patch effort, failed releases and recovery behavior, then maps each service to the platform runtime and support components under evaluation. The legacy dependency receives a time-bound exception rather than silently distorting the standard path.
The platform team supplies a trusted builder, repository template, automated tests, signed artifact promotion, service binding, identity federation, standard logs and a rollback procedure. Application teams retain authorization, data and business-rule ownership. The pilot proves a vulnerability-driven rebuild, database restoration, certificate rotation, zone disruption and platform upgrade in staging. Developers complete representative changes without platform administrators editing each deployment. Support tickets are classified so documentation, platform defects and application misunderstandings lead to different improvements.
After two release cycles, the enterprise compares commit-to-production time, build success, patch latency, incident recovery and team effort with the baseline. It also models subscription, infrastructure, platform staffing and migration cost. Services that fit move in waves; the batch and legacy cases remain on explicit paths until evidence supports change. This produces a defensible adoption decision: the platform expands where the paved road measurably improves delivery and control, while exceptions remain visible, owned and reviewable. Quarterly reviews test whether the standard still matches application demand and supported component versions.
The architecture record also names the fallback outside the platform for each critical service, the artifact and data needed to exercise it, and the owner who decides when to use it. This keeps platform confidence tied to recoverable application outcomes rather than commitment to a single supplier.
Key takeaways
- Map current component names, versions and entitlements to each promised capability.
- Choose runtimes from workload evidence and an explicit responsibility model.
- Standardize builds, provenance, identity, service binding and recovery as platform products.
- Migrate representative applications and accept them on user, data and operating evidence.
- Measure developer outcomes and lifecycle cost, then renew or narrow the platform deliberately.
Frequently asked questions
Is a Kubernetes application platform a managed service?
Not automatically. A platform provides supported software and capabilities, while the customer, the supplier or a partner may perform implementation and operation under a separate scope. Contracts must name who owns clusters, upgrades, incidents, backups and applications.
Does a Kubernetes platform eliminate lock-in?
It can standardize open technologies and application practices, but operational dependencies, proprietary services, commercial terms and migration effort remain. Test artifact portability, data export, configuration recovery and a realistic exit path rather than making an absolute portability claim.
Conclusion
Enterprise Kubernetes application platform decisions are strongest when the organization treats the platform as a maintained internal product. Establish workload fit, current commercial scope, secure build paths, service ownership and upgrade discipline before scaling. Then use production evidence to decide where the platform removes friction, where an exception is justified and whether it continues to earn its shared cost.