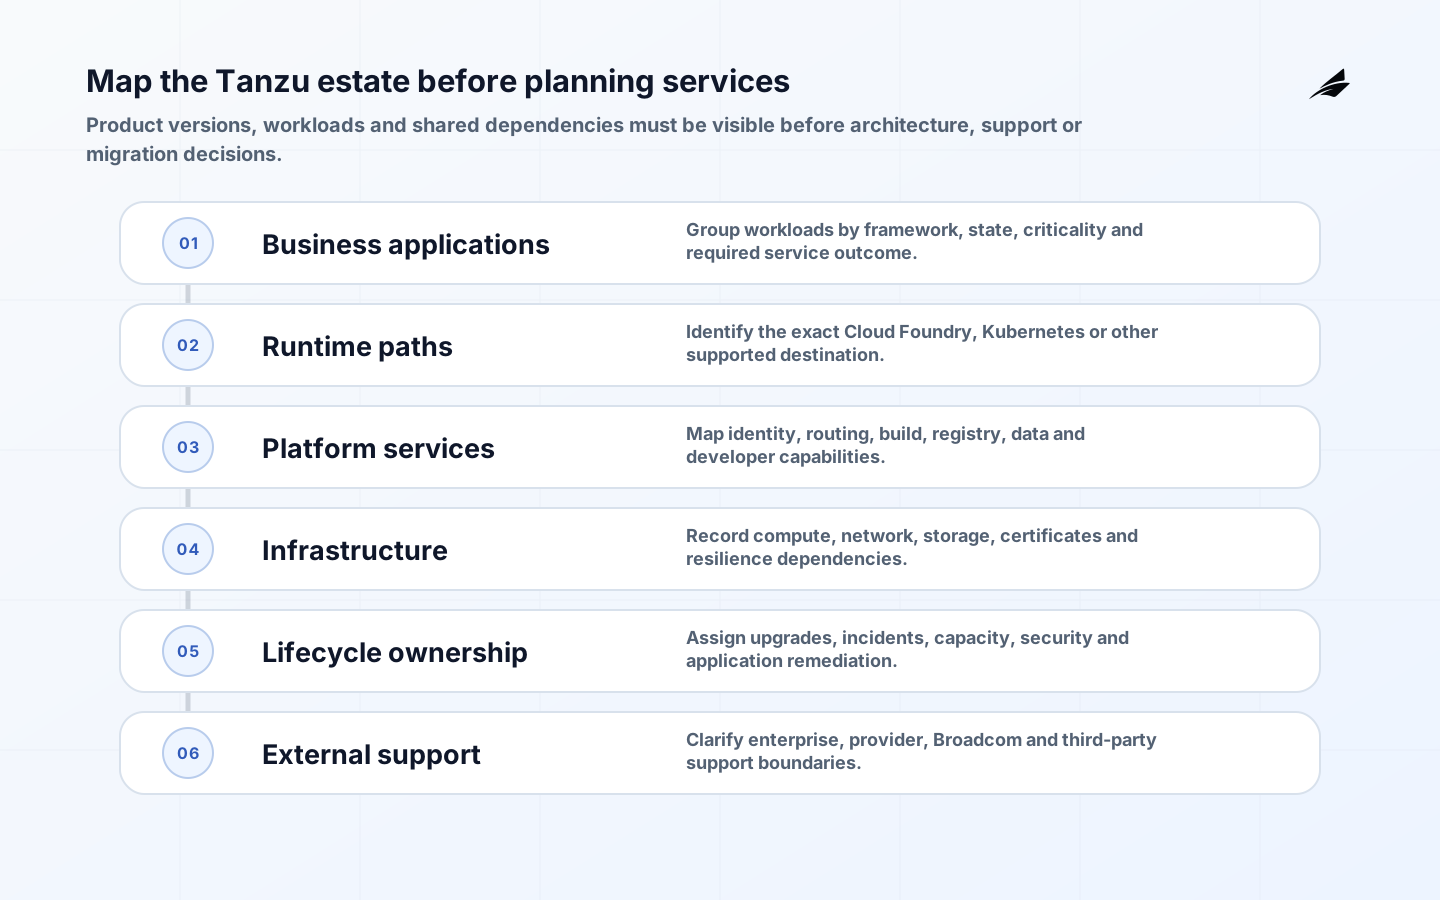
An enterprise Kubernetes application platform is an internal product, not a single interchangeable service. It may combine managed or self-run clusters, a deployment and release workflow, build and artifact controls, service routing, observability, policy and a set of shared backing services, assembled by different teams at different times. Before requesting platform services, establish the exact components, versions, entitlements, infrastructure and workloads involved. Distribution names, packaging and license terms change; architecture and commercial decisions should be checked against current supplier documentation and the enterprise's agreements.
A useful engagement is framed around an application-platform outcome: establish a supported landing zone, improve developer paths, upgrade a cluster fleet, migrate selected applications, standardize observability or create an operating model. Buying installation effort without workload and ownership planning can leave a technically running platform that teams cannot adopt, secure or support.
Define the platform estate and service boundary
Inventory the current estate from evidence. Record Kubernetes versions and distributions, clusters and environments, infrastructure, networking, identity, certificates, data services, build systems, registries, workload counts, application frameworks, dependencies, backing services and support status. Add operational evidence: incidents, capacity constraints, upgrade history, deployment paths, manual changes and recovery results. Support terms differ by component and supplier, so verify what each agreement covers and what remains an enterprise or third-party responsibility.
| Service scope | Typical outputs | Boundary to clarify |
|---|---|---|
| Assessment | Estate inventory, support and risk view, workload segmentation | Read-only access, evidence quality and Kubernetes expertise |
| Platform foundation | Target architecture, automation, identity, networking and baseline controls | Infrastructure, licenses, certificates and shared-service ownership |
| Upgrade or migration | Compatibility plan, rehearsals, waves, rollback and retirement | Application remediation and data-service responsibility |
| Developer enablement | Approved paths, templates, documentation and feedback loop | Which standards are mandatory and who maintains them |
| Managed operation | Monitoring, maintenance, incidents, capacity and service review | Coverage, exclusions, escalation and supplier coordination |
| Modernization | Application changes that improve fit or portability | Platform work versus product-team backlog |
Choose the target platform outcome
Decide whether the primary need is lifecycle support, application delivery consistency, workload portability, compliance evidence, developer experience, resilience or consolidation. Translate the outcome into measures and constraints. For example, an upgrade objective should define supported source and target versions, compatibility evidence, maintenance boundaries and rollback. A developer-experience objective should define which application types receive a paved path and how teams can extend or leave it.
- Name an accountable platform owner and the application owners affected by each wave.
- Verify current entitlements, support dates and the documentation for each component in use.
- Set availability, recovery, security and data-residency requirements per workload class.
- Define identity, network, certificate, secret and privileged-access ownership.
- Choose supported application paths without forcing every workload into one pattern.
- Document dependencies on infrastructure, service catalogs, build systems, registries and data services.
- Set portability and exit requirements for code, data, artifacts, telemetry and operational knowledge.
Application platforms sit on a spectrum. At one end, an opinionated platform-as-a-service model accepts source or an image, stages it, routes traffic and binds managed services with little per-team design. At the other, Kubernetes exposes a broader container orchestration substrate and usually requires more platform composition from the enterprise. Neither end is automatically the destination for every application. Segment workloads by runtime fit, state, dependencies, compliance, scaling and change demand, then validate representative applications.
Design platform architecture and responsibilities together
Platform architecture includes more than compute. Map traffic entry and egress, DNS, load balancing, identity federation, privileged access, image and package sources, vulnerability handling, secrets, certificates, logs, metrics, traces, backups and administrative dependencies. Identify which control is supplied by the Kubernetes distribution, underlying infrastructure, another product or an enterprise process. Avoid diagrams in which responsibility disappears inside a platform box.
A paved path should bundle a supported way to create, build, test, deploy, observe and recover a defined application type. Language and framework versions still require compatibility analysis against the runtime and base images. Provide documented extension points for teams whose workload does not fit. OpenTelemetry's model of traces, metrics and logs can help create portable telemetry, but instrumentation, semantic conventions, collection and retention still need owners.
| Control area | Platform decision | Acceptance evidence |
|---|---|---|
| Identity and privilege | Federation, roles, break-glass and service identities | Denied-path tests, access review and emergency exercise |
| Software supply chain | Approved sources, build isolation, signing and deployment policy | Traceable artifact and blocked unapproved release |
| Network | Ingress, egress, segmentation, name resolution and certificates | Flow tests, certificate rotation and failure behavior |
| Observability | Signals, ownership, retention and actionable alerts | Representative incident traced from user symptom to dependency |
| Continuity | Backup scope, restore, platform recovery and workload recovery | Timed recovery exercise with reconciled application state |
| Lifecycle | Upgrade cadence, compatibility policy and exception process | Rehearsal evidence and named remediation owners |
Estimate total platform and transition cost
Platform service cost cannot be inferred from a workload count alone. Distribution and infrastructure terms, topology, environments, availability, data services, network complexity, security assurance, application remediation, migration waves, support coverage and skills all contribute. Confirm commercial facts directly with authorized sources; do not carry forward an old bundle, edition or unit assumption. Separate one-time engagement cost, recurring platform cost, application-team work and retained legacy cost.
| Cost area | Key drivers | Evidence |
|---|---|---|
| Licensing and support | Distributions, editions, units, term and coverage | Current entitlement and quote |
| Infrastructure | Environments, topology, capacity, traffic, storage and resilience | Measured demand and target architecture |
| Platform engineering | Automation, integration, controls and lifecycle maturity | Prioritized platform backlog |
| Application work | Compatibility, framework, dependencies, state and testing | Assessment plus representative migrations |
| Migration and dual running | Wave duration, data movement, fallback and retirement | Rehearsal timings and exit criteria |
| Operation | Coverage, upgrades, incidents, observability and supplier coordination | Responsibility matrix and demand history |
Cost governance should connect consumption and service. Track platform capacity and commercial commitments alongside application adoption, deployment behavior, incidents and retained estate. Unit cost may be useful when the unit is explicit, such as a supported production application or allocated workload class. Avoid optimizing raw cluster utilization in ways that reduce resilience or make upgrades unsafe.
Example: a controlled cluster upgrade and workload wave
Consider a hypothetical enterprise whose internal services run on a Kubernetes platform that has fallen behind the supported versions. The platform needs an upgrade, while several applications still use deprecated API versions and older base image conventions, and one backing service depends on an unmanaged operator. The program first inventories ingress routes, service bindings, runtime and library versions, scheduled jobs, certificates and recovery needs. Applications are grouped into unchanged, configuration-only, dependency-remediation and redesign cohorts.
A representative application from each viable cohort is tested in a production-like cluster. The team records build output, contracts, performance, telemetry and rollback. A low-consequence wave moves first, with route and data behavior reconciled. Applications that cannot meet the gate remain on the old cluster under a time-bound exception and named remediation plan. Retirement occurs only after routes, credentials, service instances, records and recovery obligations are closed.
Control the risks that derail platform programs
| Risk | Control | Early signal |
|---|---|---|
| Ambiguous platform scope | Name components, versions and responsibilities in every deliverable | Teams use the same label for different platforms |
| Unsupported dependency | Build a compatibility matrix and test representative workloads | Unowned operator, ingress controller or data-service remediation |
| Platform without adoption | Design paved paths with product teams and measure completed journeys | Manual bypasses and low production use |
| Upgrade backlog | Fund lifecycle work and enforce time-bound exceptions | Versions drift beyond tested paths |
| Weak recovery | Separate platform and workload recovery and exercise both | Backups exist without successful restore evidence |
| Commercial or provider lock-in | Maintain entitlement clarity, portable artifacts, telemetry and transition practice | Only one party can operate or explain the estate |
A phased platform delivery plan
- Frame: confirm the business outcome, exact components, entitlements, owners and constraints.
- Discover: inventory platform components, workloads, dependencies, operations, support status and cost.
- Design: select workload paths, target controls, responsibilities, migration gates and exit requirements.
- Prove: build or upgrade a production-like slice and migrate representative applications with recovery evidence.
- Pilot: move a low-consequence wave, reconcile outcomes and test incident and supplier-escalation paths.
- Scale: migrate by cohort, track exceptions and pause when reliability or support gates are missed.
- Operate and retire: establish lifecycle reviews, transfer knowledge and remove old clusters and credentials only after evidence is complete.
Measure platform value through application-team and service outcomes: time to provision an approved path, deployment lead time, failed changes, recovery, vulnerability response, upgrade compliance, support demand and workload reliability. Pair adoption with exceptions and satisfaction; high usage achieved through mandate can conceal friction. Review supplier support cases and internal incidents together because the user experiences one service even when accountability crosses organizations.
Key takeaways
- Identify the exact platform components, versions, entitlements and workloads before buying services.
- Scope an application-platform outcome with named enterprise, provider and supplier responsibilities.
- Segment workloads by real runtime fit and validate representative applications.
- Model licensing, infrastructure, application remediation, transition and operation together.
- Use gated migration waves, practiced recovery and explicit retirement and exit evidence.
Frequently asked questions
Is an enterprise Kubernetes platform one product?
No. The term covers a stack of distinct capabilities, often from several suppliers and open source projects with different histories. Require the specific current component, version and documentation in architecture, support and commercial discussions.
Must an enterprise standardize on one application model?
Not necessarily. Different workload cohorts may justify different paths, such as an opinionated platform runtime for conventional services and direct Kubernetes access for specialized workloads. Decide from application fit, operating skills, controls, lifecycle and economics, while limiting unnecessary platform variants and defining who supports each one.
How much do enterprise Kubernetes platform services cost?
There is no universal figure. Verify current commercial terms, then estimate assessment, architecture, infrastructure, controls, application remediation, migration, training, support and retained estate. Representative workload evidence narrows the range.
What should a platform services provider hand over?
Expect current architecture and decision records, automation and repositories, configuration and access inventories, compatibility evidence, runbooks, recovery results, known risks, workload status and demonstrated operational knowledge. Match deliverables to the agreed responsibility model.
Conclusion
Kubernetes platform services create value when component specificity, application needs and operating ownership meet. Inventory the real estate, choose workload paths from evidence, design controls and lifecycle work into the platform, and migrate through reversible waves. The durable outcome is not an installed platform; it is a supported application service the enterprise can understand, operate and evolve.