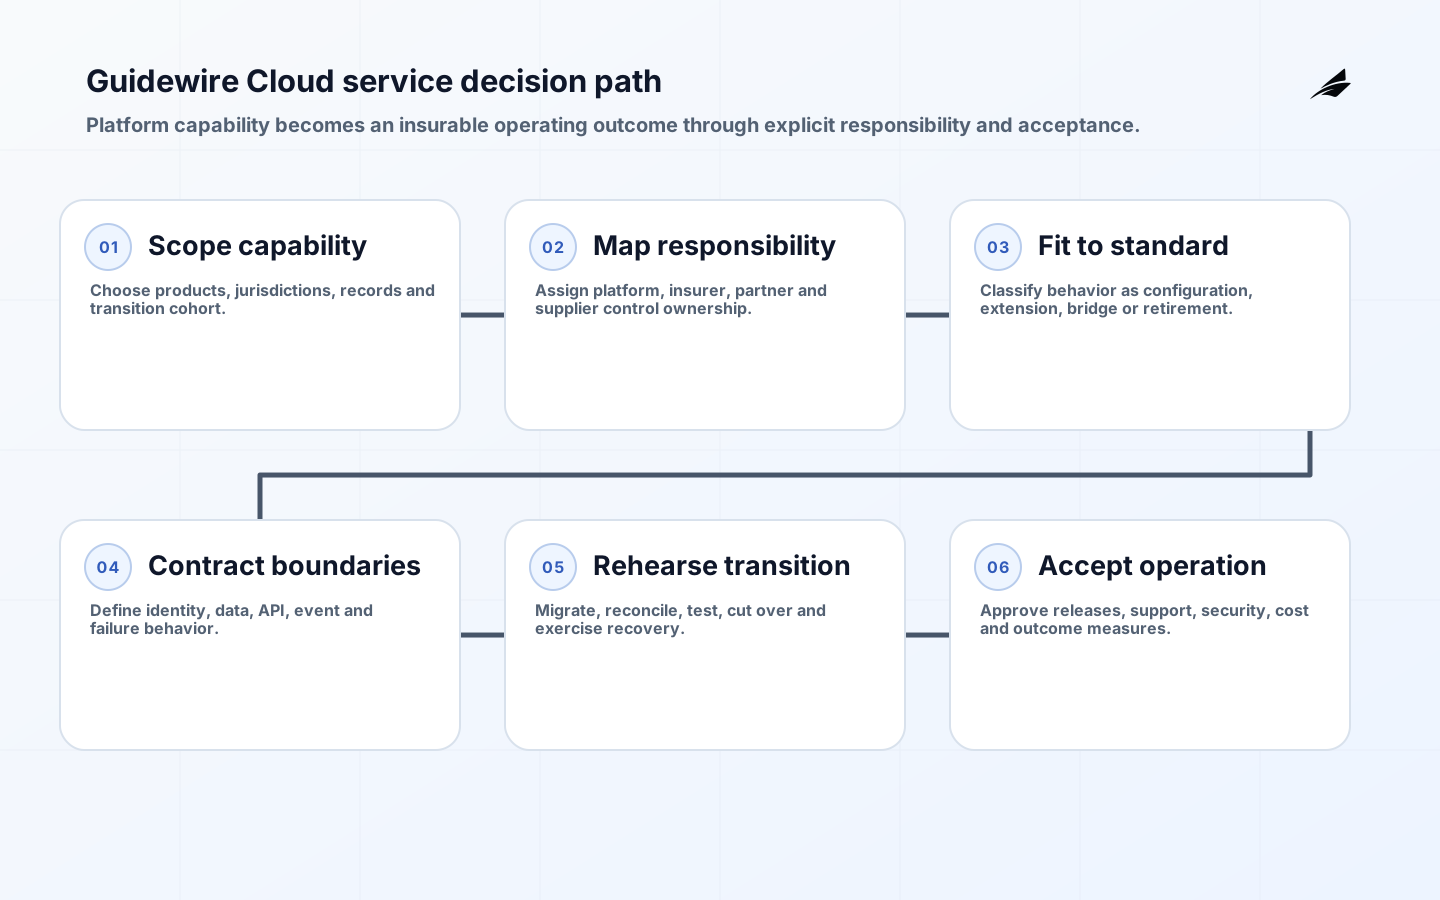
Managed cloud services for an insurance core platform combine provider-operated platform capabilities with insurer-owned configuration, integrations, data governance and operating decisions. The central buying question is therefore not simply whether infrastructure moves to a provider’s cloud. It is whether the insurer can modernize policy, billing or claims workflows while retaining clear authority over controls, releases, downstream systems and customer outcomes.
This FAQ is for P&C technology leaders, architects, delivery owners and control functions evaluating or preparing a program. Use it with the scope and delivery plan for managed cloud services, the implementation checklist and the core-system cloud migration plan. It stays vendor-neutral and concentrates on running the service. Product capabilities and commercial terms change, so confirm release-specific details in current provider documentation and the contract.
What does the provider run, and what stays with the insurer?
A managed cloud platform typically covers infrastructure, runtime and platform services for building, deploying, testing, authentication, monitoring and data access. That removes substantial infrastructure work, but it does not transfer accountability for insurance products, workflow design, access decisions, integration behavior, data quality or regulatory obligations. Draw a responsibility matrix for each environment and control rather than relying on a generic cloud statement. The NIST definition of cloud computing (SP 800-145) offers shared vocabulary for service models.
Cloud security guidance, including NIST SP 800-144, presents a shared-responsibility model in which the customer remains accountable for its data, configurations and access. A program therefore needs owners for identity federation, role design, production support, secrets introduced by integrations, lower-environment data, retention, audit evidence and provider oversight. Contract language, architecture and runbooks should express the same boundary.
| Capability | Provider contribution | Insurer decision and evidence |
|---|---|---|
| Cloud runtime | Managed platform, environments and platform operations | Approved topology, service targets and dependency plan |
| Application configuration | Supported development and deployment toolchain | Product rules, extensions, code quality and ownership |
| Identity | Platform authentication and integration options | Identity provider, lifecycle, roles and access reviews |
| Data protection | Platform security and compliance capabilities | Classification, permitted use, residency, masking and retention |
| Integrations | Documented APIs and integration patterns | Contract, idempotency, monitoring and downstream recovery |
| Release and incident management | Build promotion, deployment facilities and platform incident handling | Acceptance suite, change authority, business impact decisions and customer communication |
How should we scope the managed service?
Scope by business capability and data journey, not by a count of screens or interfaces. Inventory products, jurisdictions, active and historical records, documents, payments, correspondence, reports, batch processes, users and partners. For each, decide whether to host it in the service, rebuild, integrate, archive or retire. Then fix the service terms that follow: environments included, support hours, regions, data residency and peak capacity. A claim may be technically loaded yet unusable if its notes, financial history, documents or policy context are missing.
Choose an onboarding unit that operations can validate and support: a line of business, region, new business cohort or bounded claim segment. Define coexistence explicitly. During transition, state which system owns policy, billing, claim, party and financial status; how late changes synchronize; and how a customer or adjuster sees one coherent history. A single-step move can be appropriate in constrained circumstances, but it should be a risk decision supported by rehearsal rather than a default ambition.
How much should we configure or customize?
Prefer supported configuration, extension points, documented APIs and packaged integrations when they satisfy the outcome. Custom code is justified when it protects a material differentiator or unavoidable obligation and has a named lifecycle owner. Every extension should document the business rule, interface, data touched, failure behavior, automated tests and release-compatibility evidence. Recreating legacy behavior without asking why it exists preserves cost rather than capability.
Use a fit-to-standard workshop around real cases, including exceptions. Ask an adjuster or underwriter to complete the workflow and identify where standard behavior changes policy, service or control outcomes. Classify each gap as mandatory, valuable, temporary or obsolete. Require approval for mandatory deviations and an expiry date for temporary bridges. This keeps the backlog tied to business decisions instead of stakeholder familiarity.
How should integrations and network connectivity work?
Treat each integration as a product with a contract and service owner. Providers commonly offer several connectivity patterns, such as public TLS connections and private links; ask which are supported and who operates each end. Select the pattern from data sensitivity, latency, throughput, availability and operational constraints. Do not assume a private path fixes weak authentication or poor message design.
For APIs and events, define source authority, schema version, authentication, authorization, timeout, bounded retry, idempotency key, ordering needs, reconciliation and a dead-letter process. Avoid synchronous chains across many legacy systems for a customer-facing transaction. Where an external service is unavailable, preserve the insurance intent and expose an operational state instead of silently losing work or repeating a payment, document or notification.
| Integration question | Design evidence | Failure acceptance |
|---|---|---|
| Who owns the record? | Field-level source-of-truth map | No conflicting updates during coexistence |
| Can a request repeat? | Stable idempotency key and replay test | Duplicate has no additional business effect |
| What if the dependency is slow? | Timeout, queue or degraded-path decision | User and operator can see pending state |
| How is change managed? | Versioned contract and consumer tests | Old and new versions coexist for agreed window |
| How is completeness proven? | Counts, totals and exception reconciliation | Every break enters an owned queue |
| How is access revoked? | Workload identity and credential inventory | Compromised identity can be isolated promptly |
How do releases and upgrades affect delivery?
A managed service changes upgrade work from occasional transformation to continuing product stewardship. Review the provider’s release notes on a fixed cadence. Assess changes against configured workflows, extensions, integrations, data pipelines, controls and training materials. Maintain a regression inventory by business consequence so testing effort follows exposure rather than application size.
Ask the provider how development, preproduction and production use are separated and how build promotion works. Define who may build, promote and deploy and what requires business approval. Agree how much notice the provider gives of a change and whether the insurer can defer it. Rehearse a representative release with data migration, smoke tests, integration checks and communications. The rollback plan must account for records written after exposure, not only application binaries.
What security and data controls need explicit design?
Start with the provider’s security documentation and map it to the insurer’s policies and jurisdictional duties. Federate workforce identity, automate joiner-mover-leaver flows, minimize privileged roles and separate routine administration from emergency access. Test authorization through business operations: viewing a claim, changing reserves, approving payment, exporting records and modifying configuration are distinct privileges.
Inventory sensitive data and integration flows, and keep unapproved production personal data out of lower environments. Define masking or synthetic-data patterns, document export controls, monitor bulk access and propagate retention or legal holds through connected stores. Confirm region, subprocessor, encryption, backup, restoration and evidence obligations contractually. Insurance data security rules such as the NAIC model law expect due diligence in selecting service providers.
What testing proves production readiness?
Build acceptance around insurance outcomes. Test quote or policy changes, billing consequences, first notice of loss, coverage verification, reserves, payments, recovery, correspondence and closure as applicable. Include permission denial, duplicate requests, catastrophe volume, an inaccessible dependency and manual correction. Reconcile financial totals and record counts independently; a successful API response does not prove accounting or operational completeness.
Run at least one production-like rehearsal with measured duration. Validate data load, document availability, reconciliation, identity, integrations, reports, operational queues and monitoring. Restore from backup and, where the design allows, fail over, then compare measured recovery time and recovery point with the contract; NIST SP 800-34 offers a structure for recovery plans and exercises. Define go/no-go thresholds and decision authority before the rehearsal, and give cutover a command structure and a bounded hypercare exit criterion.
How should cost, service levels and success be measured?
Model total program cost across subscription, implementation, data remediation, integration replacement, testing, environments, network services, partner capacity, training, decommissioning and ongoing release stewardship. Separate one-time transition cost from steady-state operation. Ask how usage-based platform resources are measured and alerted, and assign an owner for forecasts and anomalous consumption.
Define success by operating outcomes: cycle time by claim or policy segment, straight-through completion with quality, payment accuracy, leakage indicators, customer contact, adjuster workload, release lead time, failed changes, service recovery and control exceptions. Baseline before onboarding and segment results so portfolio changes do not masquerade as system improvement. Compare the provider’s service-level reports with the insurer’s own observations. Include adoption and workaround measures; staff exporting data to spreadsheets can conceal a poor workflow.
- Confirm business outcomes, products, jurisdictions and the onboarding unit.
- Approve the shared-responsibility, data and environment model.
- Classify legacy behavior as standard fit, justified extension, bridge or retirement.
- Contract every integration and rehearse its failure and reconciliation paths.
- Prove data loading, security, insurance journeys, recovery and financial completeness.
- Cut over with named authority, observable thresholds, agreed exit terms and a funded operating model.
Key takeaways
- A managed cloud platform does not remove insurer accountability for configuration, data, access or outcomes.
- Scope the service by business capability, authoritative data and coexistence behavior.
- Use supported configuration and interfaces unless a justified deviation has lifecycle ownership.
- Design releases, regression evidence, recovery testing and operating readiness as continuous capabilities.
- Measure customer, insurance, financial and control outcomes rather than activity or availability alone.
Frequently asked questions
How long does onboarding to the service take?
There is no defensible universal duration. Product count, jurisdictional variation, legacy data quality, integration estate, customization, testing evidence and transition strategy drive the plan. Estimate each onboarding slice from verified inventory and a pilot, then include remediation, rehearsal and business readiness rather than quoting configuration effort alone.
Do we need an implementation partner?
Many insurers use specialists for product and onboarding depth, but the insurer must retain architecture, product, data, control and acceptance authority. Contracts should define named skills, deliverable ownership, knowledge transfer, environment access and exit. Test transfer by having the internal team operate and release a representative change.
How do we exit the service if we need to?
Plan the exit at signing, not at termination. Agree the export format and timing for data, documents and configuration, how long the provider keeps the environment running during transition, what that help costs and how deletion is confirmed. Test the export on a sample and keep current source and configuration under insurer control, so that leaving is an engineering task rather than a negotiation.
Conclusion
Managed cloud services for an insurance core platform succeed when provider capability, insurance process and operating accountability are designed together. Make boundaries explicit, reduce unjustified legacy behavior, contract integrations, prove data, recovery and control outcomes, and prepare for continuous releases. That creates a service the insurer can govern after the delivery team leaves.