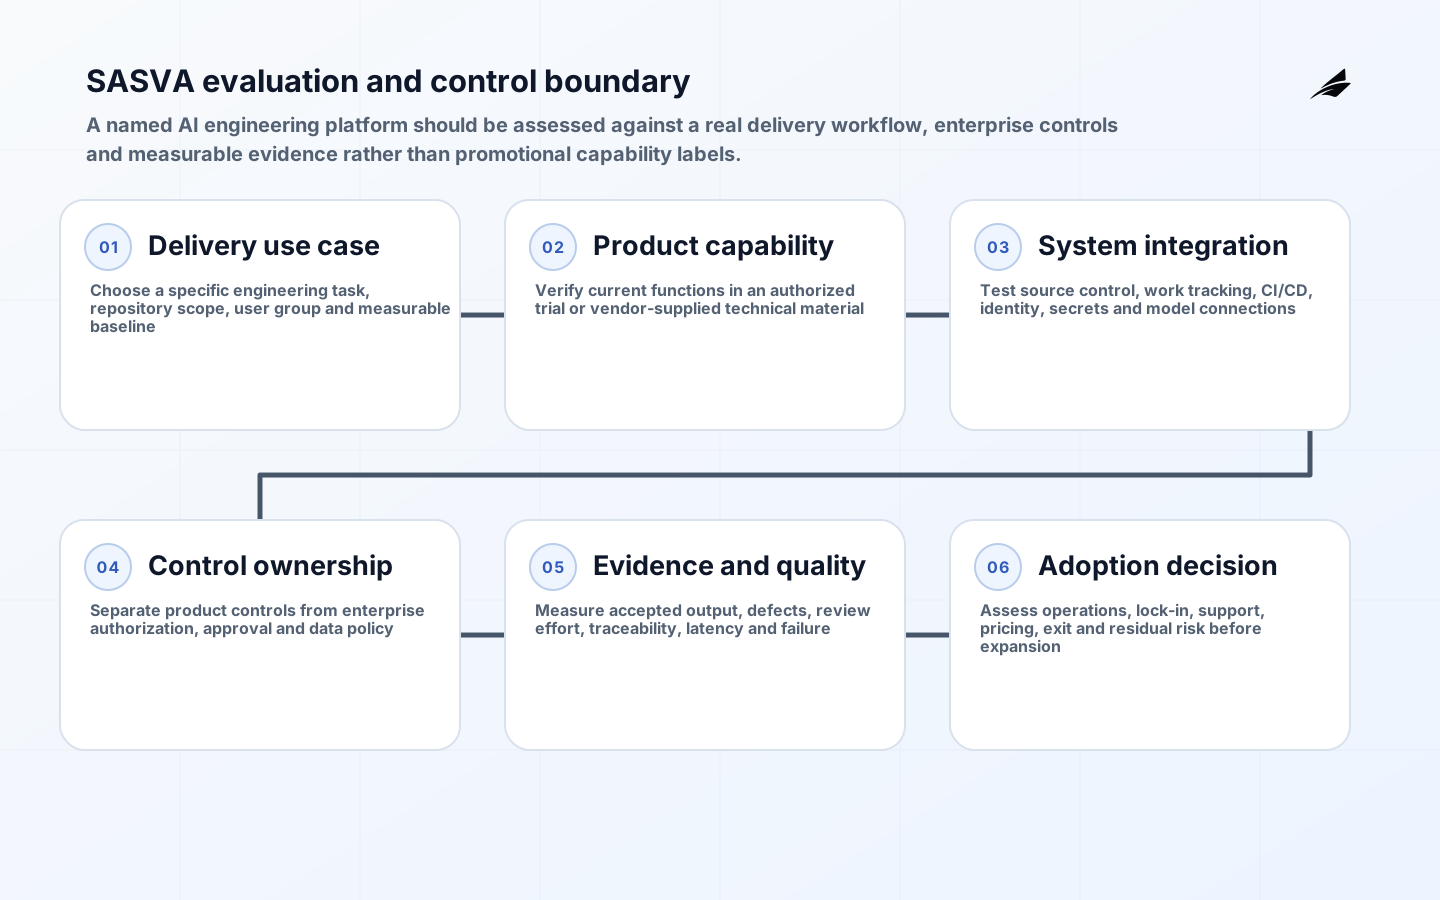
An AI-assisted software engineering platform needs a precise identity and service boundary before any estimate is useful. For an enterprise evaluating such a platform for team-based AI engineering, the practical objective is to improve planning, modernization, development, testing or support with governed context and verifiable engineering outcomes rather than counting generated artifacts. That requires decisions about the selected lifecycle use case and its baseline, the repository, ticket, document and dependency context the platform may read, and the design-time control layer and workflow guardrails that constrain agents, followed by evidence that the resulting service works under normal load, failure and change. A product name, analyst assessment or consulting label can narrow the subject, but it cannot replace workload discovery, accountable ownership or acceptance tests. The team should record assumptions, exclusions and decision authority before asking vendors or delivery teams for estimates.
The governing boundary is equally important: a platform can coordinate people, agents, models and engineering context, but the enterprise still authorizes repositories, models, infrastructure, quality gates, releases and accountable decisions. This distinction shapes architecture, contract terms, access, testing and incident response. It also prevents a familiar failure in which each party performs its assigned activity but nobody owns the end-to-end outcome. Readers who need adjacent context can use the implementation checklist for AI-assisted software engineering platforms to compare this scope with a pilot-level view of the same topic.
Key takeaways
- Name the outcome in operational terms: improve planning, modernization, development, testing or support with governed context and verifiable engineering outcomes rather than counting generated artifacts.
- Document the responsibility boundary. A platform can coordinate people, agents, models and engineering context; the enterprise still authorizes repositories, models, infrastructure, quality gates, releases and accountable decisions.
- Design around the real components: the selected lifecycle use case and baseline; repository, ticket, document and dependency context; and the design-time control layer and workflow guardrails.
- Treat granting broad code or ticket access before data classification, and using stale architecture context to recommend unsafe changes, as testable delivery risks rather than footnotes.
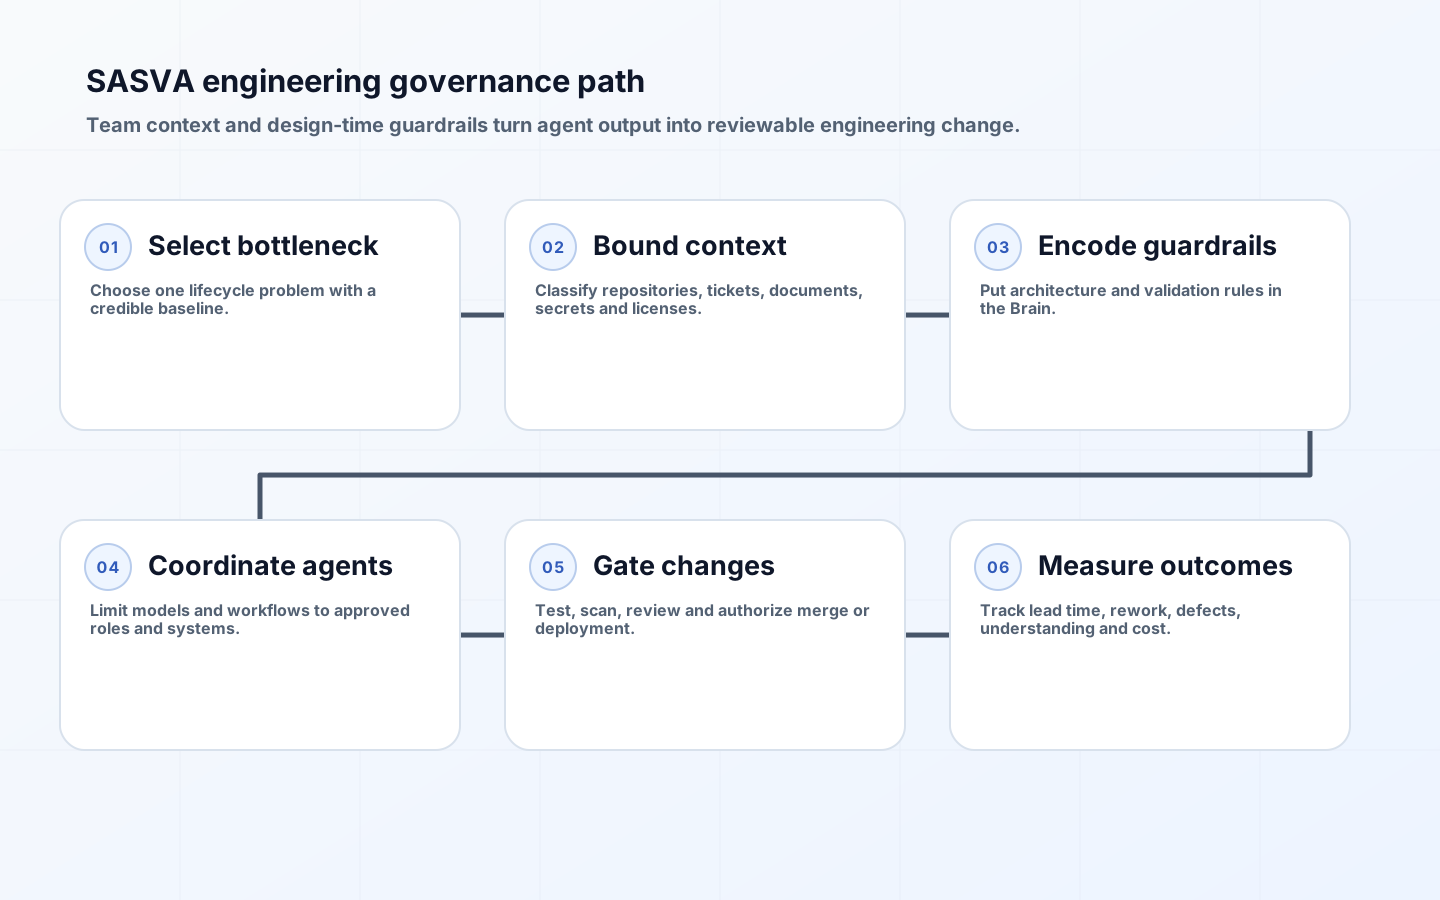
- Install operating controls, including starting with one repository family and one measurable engineering bottleneck, and inventorying secrets, licenses, personal data and export restrictions before ingestion.
- Measure lead time from approved work to production, review acceptance and substantive rework, and escaped defect and rollback rate together, so that one metric cannot hide a degraded journey.
Define scope and decision authority
Start discovery with representative work, not a generic capability inventory. Trace one normal journey, one high-value journey, one exception and one recovery path through the selected lifecycle use case and baseline, the repository, ticket, document and dependency context, and the design-time control layer and workflow guardrails. For every step, record the initiating actor, authoritative record, business rule, permission, dependency, expected result and evidence of completion. This exposes whether the proposed scope includes the difficult seams or merely the visible interface. It also gives estimators concrete volumes, variants and nonfunctional conditions rather than a list of aspirational features.
Decision authority should follow consequence. A product or service owner approves outcomes and customer policy; data owners approve meaning, retention and permitted use; security owners approve control requirements; engineering owners approve technical fitness; operations owners accept monitoring and recovery. A supplier can recommend a choice, but acceptance remains with the party carrying the consequence. Record time-bounded delegations for cutover and incidents. When a decision is deferred, keep its assumption, owner, latest decision date and affected backlog visible rather than silently converting uncertainty into scope.
Design the architecture and operating boundary
The architecture should show both movement and authority. Map the selected lifecycle use case and baseline; repository, ticket, document and dependency context; the design-time control layer and workflow guardrails; model and infrastructure selection; IDE, CI/CD, service-management and knowledge integrations; and evaluation, staged rollout and operating ownership as connected responsibilities. Mark where identity changes, data crosses a trust boundary, asynchronous work begins, a human must decide, or an external service can delay completion. Each boundary needs a contract: inputs, outputs, authentication, validation, timeout, retry behavior, observability and ownership. The diagram should also identify the system of record and the mechanism used to reconcile downstream state after partial failure.
| Architecture area | Required design decision | Acceptance evidence |
|---|---|---|
| Lifecycle use case and baseline | Choose ownership, boundary and supported pattern for the lifecycle use case and its baseline; address the risk of granting broad code or ticket access before data classification. | Demonstration, configuration record and failure test proving that the pilot starts with one repository family and one measurable engineering bottleneck. |
| Repository, ticket, document and dependency context | Choose ownership, boundary and supported pattern for repository, ticket, document and dependency context; address the risk of using stale architecture context to recommend unsafe changes. | Demonstration, configuration record and failure test proving that secrets, licenses, personal data and export restrictions are inventoried before ingestion. |
| Design-time control layer and workflow guardrails | Choose ownership, boundary and supported pattern for the control layer and workflow guardrails; address the risk of accepting generated code because it compiles, without behavioral evidence. | Demonstration, configuration record and failure test proving that architectural constraints and required checks are encoded before agent execution. |
| Model and infrastructure selection | Choose ownership, boundary and supported pattern for model and infrastructure selection; address the risk of allowing agent workflows to merge or deploy beyond reviewed authority. | Demonstration, configuration record and failure test proving that tests, security scans, dependency review and human approval run outside model claims. |
Prefer reversible change and explicit interfaces. A small first slice should still use production-grade identity, telemetry, deployment and support paths; otherwise the pilot proves only that a demo can run. Separate configuration from code, secrets from artifacts and business policy from transport logic. Version material inputs and outputs so an incident can be reconstructed. Capacity design must include peaks, provider quotas, queues and back-pressure. Recovery design must restore a coherent business state, not just restart infrastructure while duplicate, missing or inconsistent work remains.
Sequence delivery with evidence gates
Organize delivery around thin, end-to-end increments. The first increment should exercise the selected lifecycle use case and baseline, the design-time control layer and workflow guardrails, and evaluation, staged rollout and operating ownership with a small but representative population. It must include access, logging, error handling, support and reconciliation from the beginning. Expand only after the team can explain defects and operate the slice. This sequencing discovers integration and ownership problems while rollback is affordable. It also gives users something complete enough to evaluate, rather than disconnected technical components whose combined behavior remains unknown until broad rollout.
| Gate | Evidence to review | Stop condition |
|---|---|---|
| Baseline | Measured lead time from approved work to production, and review acceptance and substantive rework, with volumes and exceptions. | No agreed starting point or outcome owner. |
| Design | Traceable decisions for the lifecycle use case and baseline, model and infrastructure selection, and IDE, CI/CD, service-management and knowledge integrations. | Critical boundary or authority remains implicit. |
| Pilot | Representative success, failure, security and recovery tests. | Team cannot diagnose or reconcile a failed journey. |
| Scale | Stable escaped defect and rollback rate, test coverage of changed behavior and support ownership. | Exceptions grow faster than owners can resolve them. |
| Handover | Runbooks, access, dashboards, knowledge and supplier routes exercised. | Permanent team depends on project-only people or credentials. |
A gate is a decision point, not a status meeting. Name the approver, evidence, tolerance and options: proceed, correct, reduce scope or stop. Rehearse each expansion step against production-like volumes and access. Include communications, freeze decisions, rollback criteria and cost reconciliation. After release, keep a bounded hypercare period with a declining entry threshold and explicit exit criteria. Open defects and workarounds must transfer to permanent owners with priority, due date and observable risk.
Install security, quality and operating controls
Security begins with inventory and least privilege. Classify data and code before granting access, separate human from workload identities, use short-lived credentials where supported and log privileged actions with an approved purpose. Validate inputs at trust boundaries and enforce authorization at the service performing the action. Encryption and attestations matter, but they do not correct excessive permissions or unclear processing. Review suppliers, subprocessors and regional handling against the actual flow, then test access removal and emergency access rather than accepting policy text alone.
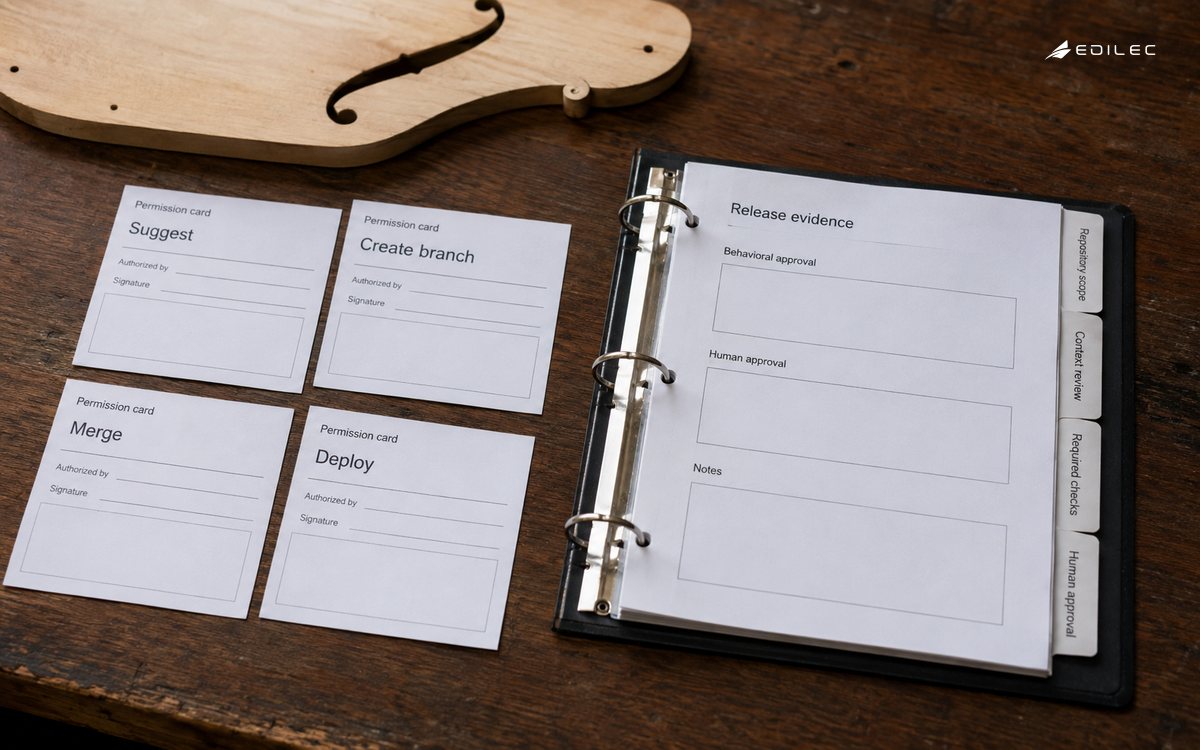
Quality controls must cover business behavior and operational behavior. Start with one repository family and one measurable engineering bottleneck, inventory secrets, licenses, personal data and export restrictions before ingestion, and encode architectural constraints and required checks before agent execution. Then verify that tests, security scans, dependency review and human approval run outside model claims, keep suggestion, branch creation, merge and deployment permissions separate, and measure accepted outcomes, rework, defects and cost per completed change. Test normal, boundary, concurrent, degraded and recovery conditions. Preserve test data provenance and expected outcomes. A production control needs an owner, trigger, response, evidence and review cadence; a dashboard without an action rule is only a display. Where manual review is required, design workload, queue priority, evidence and escalation so reviewers can make a real decision.
- 1. Start with one repository family and one measurable engineering bottleneck. For this control, name the accountable owner, supporting evidence, exception route and next measurable check.
- 2. Inventory secrets, licenses, personal data and export restrictions before ingestion. Within this control, name the accountable owner, supporting evidence, exception route and next measurable check.
- 3. Encode architectural constraints and required checks before agent execution. When implementing this control, name the accountable owner, supporting evidence, exception route and next measurable check.
- 4. Run tests, security scans, dependency review and human approval outside model claims. Before releasing this control, name the accountable owner, supporting evidence, exception route and next measurable check.
- 5. Separate suggestion, branch creation, merge and deployment permissions. While operating this control, name the accountable owner, supporting evidence, exception route and next measurable check.
- 6. Measure accepted outcomes, rework, defects and cost per completed change. When changing this control, name the accountable owner, supporting evidence, exception route and next measurable check.
Measure value, reliability and cost together
Build a measurement tree from the intended outcome to user, process, technical and cost signals. Track lead time from approved work to production, and review acceptance and substantive rework, as outcome or flow measures; pair them with escaped defect and rollback rate and test coverage of changed behavior to expose quality and control effects. Use cost per accepted engineering outcome, together with developer understanding, handoff quality and support resolution, to test whether the service remains economical and recoverable. Define formula, source, population, exclusion, frequency and owner for every measure. Segment results where different journeys or affected groups can experience materially different performance.
Do not declare value from activity counts alone. More generated artifacts, automated steps or logins can coexist with greater rework. Compare against a credible baseline and include transition labor, dual running, licenses, support and exception handling. Review leading signals such as queue age, unresolved decisions and expiring access beside lagging outcomes. When results miss tolerance, the governance forum should choose an action and owner; explanations without a funded correction are not benefits realization.
Frequently asked questions
- What belongs in the first release? Choose one representative journey that crosses the most important boundary, has an accountable owner and can be reversed without unacceptable harm.
- How detailed should the contract or charter be? It should name eligible scope, exclusions, responsibilities, evidence, service targets, change treatment, data handling, exit rights and acceptance authority.
- When is customization justified? Use it when a differentiated or mandatory rule cannot be met safely through supported configuration, and fund its testing, upgrade and retirement obligations.
- What proves production readiness? Real personas complete normal and exception work; telemetry reaches an owner; recovery and reconciliation are exercised; access and support paths work without project-only privileges.
- How should a vendor claim be assessed? Confirm the exact edition and date, request evidence for the buyer's scenario, validate references and run a controlled proof using the intended data and interfaces.
- What should trigger a pause? Unowned critical risk, irreconcilable data, missing authorization, failed recovery, unclear rollback or a material outcome below its agreed safety threshold.
Conclusion
A defensible AI-assisted engineering platform plan turns a broad label into a bounded service with tested responsibilities. Begin with the outcome of improving planning, modernization, development, testing or support with governed context and verifiable engineering results rather than counting generated artifacts; map the complete journey; then make architecture, delivery and operating decisions visible. The most credible plan does not promise that every uncertainty disappears. It shows who decides, what evidence is required, how failure is contained and how the organization will learn. If the team can operate the first representative slice, reconcile its records, explain its cost and reverse a bad change, it has a foundation worth scaling.